Rental scams are one of the oldest problems in real estate, and the internet has made them faster and cheaper to run. A scammer copies photos from a real listing, reposts them at a below-market price, and asks for a deposit before a viewing. Renters lose money, real owners and agents get angry calls, and listing platforms lose trust. The good news is that the same AI tools that make scams easier to produce can also make them easier to catch. This guide shows how property managers, small brokerages, and listing site operators can build a practical AI-assisted fraud screening workflow without a data science team.
Why Rental Listing Fraud Is Hard to Catch Manually
Fake listings rarely look fake. They usually reuse real photos, real addresses, and realistic descriptions. The warning signs are spread across several places at once:
Price: rent that is far below comparable units in the same area.
Images: photos that already appear on another listing, often with a different city or contact.
Text: urgency, requests to communicate off-platform, or payment by wire transfer, gift cards, or crypto.
Account behavior: new accounts posting many listings quickly, or contact details reused across unrelated properties.
A human reviewer can check one or two of these signals per listing. AI is useful because it can check all of them, every time, and hand the reviewer a short explanation instead of a raw listing.
Step 1: Define What You Are Screening For
Before choosing tools, write down your rules in plain language. This becomes the backbone of both your automated checks and your prompts. A good starting list:
Listing rent is significantly below the median for similar units nearby (you choose the threshold).
One or more photos match images already in your database under a different listing or owner.
The description asks for payment before a viewing or lease signing.
The poster asks to move the conversation to personal email or a messaging app.
The same phone number or email appears on listings in unrelated locations.
Keep the rules specific. Vague goals like "find suspicious listings" produce vague results from any model.
Step 2: Catch Reused Photos With Image Similarity
Duplicate photos are one of the strongest fraud signals, and they are also the easiest to automate.
Perceptual hashing for exact and near-duplicates
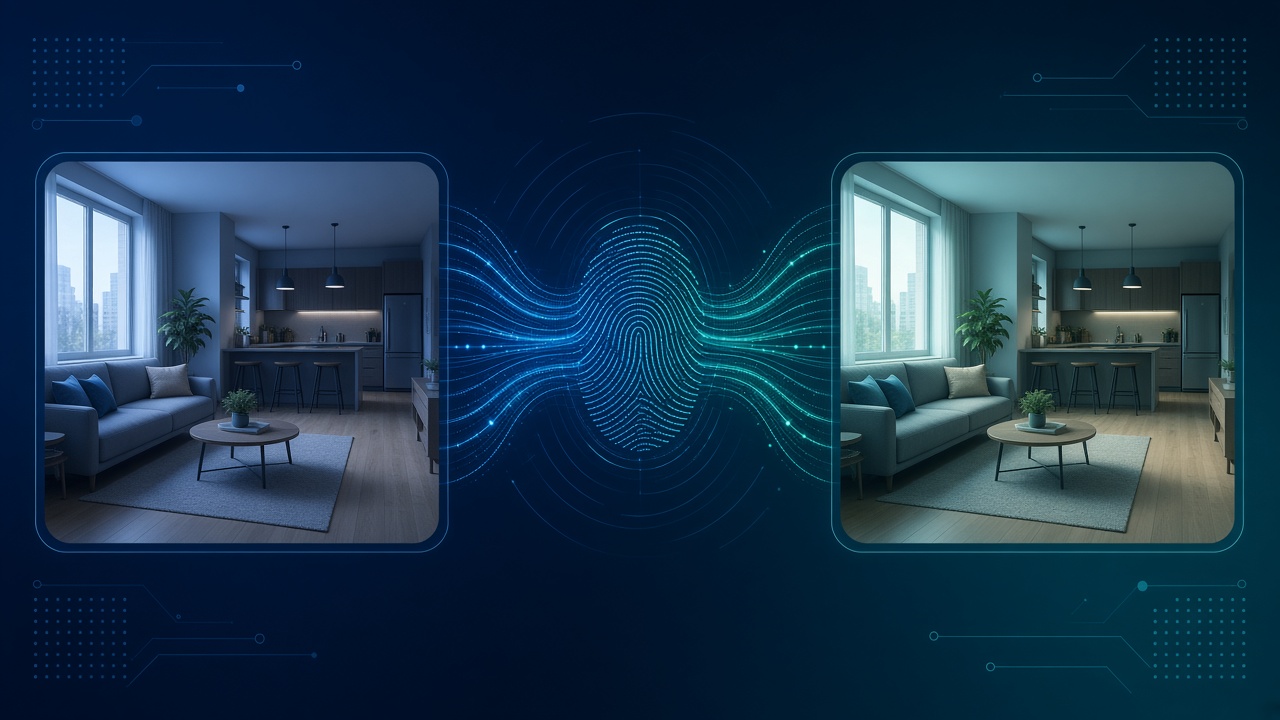
Perceptual hashes (such as pHash or dHash) turn an image into a short fingerprint that stays similar even when the image is resized, recompressed, or slightly cropped. In Python, the open-source imagehash library can compute these in a few lines. Store the hash for every uploaded photo, and when a new listing arrives, compare its hashes against existing ones. A small Hamming distance between two hashes means the photos are likely the same.
Embeddings for heavier edits
Scammers sometimes flip, crop, or filter photos to defeat simple matching. Image embedding models (for example, open CLIP-style models) convert images into vectors that capture visual content. Store those vectors in a vector database or an extension such as pgvector for PostgreSQL, and run a nearest-neighbor search for each new photo. Matches above your similarity threshold go to review.
Start with hashing; it is cheap and explainable. Add embeddings only if you see edited duplicates slipping through.
Step 3: Flag Price Anomalies
You do not need a complex valuation model to spot a listing that is too cheap. A simple approach works well:
Group your active and recent listings by area (postal code or neighborhood), bedroom count, and property type.
Calculate the median rent for each group.
Flag new listings priced well below that median, for example 30 to 40 percent lower. Tune the number with your own data.
If you have enough history, a gradient-boosted model or an isolation forest from scikit-learn can learn a more nuanced picture of normal pricing. Either way, treat a low price as one signal, not a verdict. Genuine bargains exist.
Step 4: Use a Language Model to Read the Listing Text
Large language models are well suited to reading descriptions and messages for scam patterns, because those patterns are about intent and phrasing rather than keywords. Instead of a keyword blocklist, send the listing text to a model with a structured prompt.
A practical prompt pattern
Ask the model to return structured output, such as JSON, with fields like:
risk_level: low, medium, or high.
signals: a list of specific red flags found, each quoting the relevant phrase.
explanation: one or two sentences a reviewer can read quickly.
Include your rules from Step 1 in the prompt and tell the model to report only signals it can point to in the text. This reduces made-up reasoning and makes the output auditable. Most major model APIs support structured or JSON output modes, which makes the response easy to parse.
Watch for privacy and cost
Strip personal data you do not need, such as renter names in message threads, before sending text to an external API. Check your provider's data retention terms. To control cost, run the language model only on listings that pass cheap checks first, or on all listings but with a smaller, faster model.
Step 5: Combine Signals Into a Review Score
Each check on its own produces false positives. Combined, they become much more reliable. A simple weighted score is enough to start:
Assign points for each signal: a duplicate photo might be worth more than a slightly low price.
Add the language model's risk level as another weighted input.
Add account signals, such as account age and number of listings posted in the last day.
Route listings above a threshold to a human review queue, and hold the highest-risk ones from publishing until reviewed.
Show reviewers why a listing was flagged, including the matching photo, the comparable median rent, and the quoted text. Reviewers decide faster and more accurately when they can see the evidence.
Step 6: Keep Humans in the Loop and Measure Results
Automated screening should support decisions, not make final ones, especially when a wrong call blocks a real landlord or agent. Build in a few habits:
Log every decision and the reason, so you can audit and improve rules.
Track false positives and misses each month and adjust thresholds based on your own data.
Give users a way to report listings, and feed confirmed reports back into your rules and photo database.
Review for fairness. Make sure rules do not penalize listings in particular neighborhoods or languages without a real fraud basis.
A Simple Starter Stack
You can build a working first version with common, well-documented tools:
Python for the pipeline, with imagehash and Pillow for photo fingerprints.
PostgreSQL with pgvector for listing data and image embeddings.
pandas or SQL for neighborhood rent medians, and scikit-learn if you want anomaly detection.
A language model API with structured output for text analysis.
A serverless function or background job queue to run checks whenever a listing is created or edited.
Final Thoughts
Rental fraud thrives on speed and volume, which is exactly where AI screening helps. Start small: hash photos, compare prices with local medians, and have a language model explain risky text. Combine these into a clear score, keep a human reviewer in charge of final decisions, and refine the system with real outcomes. Even a basic version can stop many fake listings before a renter ever sends a deposit, and that protects your business's reputation as much as your users' money.